推荐学习书目
› Learn Python the Hard Way
Python Sites
› PyPI - Python Package Index
› http://diveintopython.org/toc/index.html
› Pocoo
值得关注的项目
› PyPy
› Celery
› Jinja2
› Read the Docs
› gevent
› pyenv
› virtualenv
› Stackless Python
› Beautiful Soup
› 结巴中文分词
› Green Unicorn
› Sentry
› Shovel
› Pyflakes
› pytest
Python 编程
› pep8 Checker
Styles
› PEP 8
› Google Python Style Guide
› Code Style from The Hitchhiker's Guide
1722332572
V2EX  ›  Python

[不分词版]Chinese-Text-Classification: Tensorflow CNN 模型实现的中文文本分类器

  •  
  •   1722332572 · Nov 10, 2017 · 3912 views
    This topic created in 3247 days ago, the information mentioned may be changed or developed.

    从现在的结果来看,分词的版本( https://www.v2ex.com/t/404977#reply6 )准确率稍微高一点。

    项目地址: https://github.com/fendouai/Chinese-Text-Classification

    jieba 分词的版本在 master 分支,不分词的版本在 dev 分支。

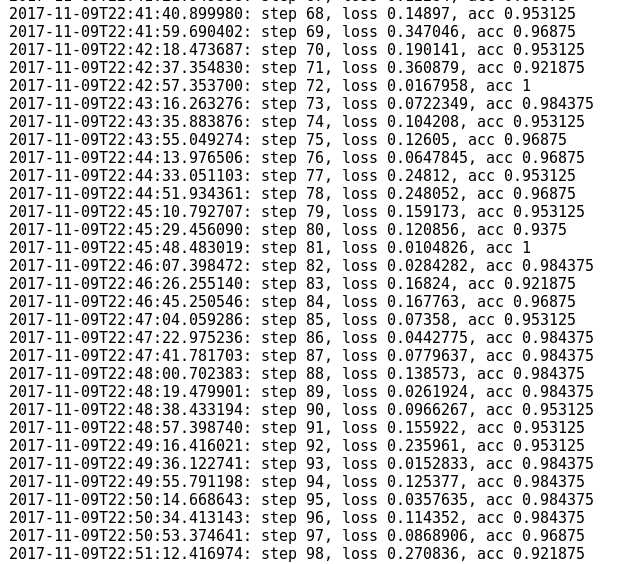
    训练过程:
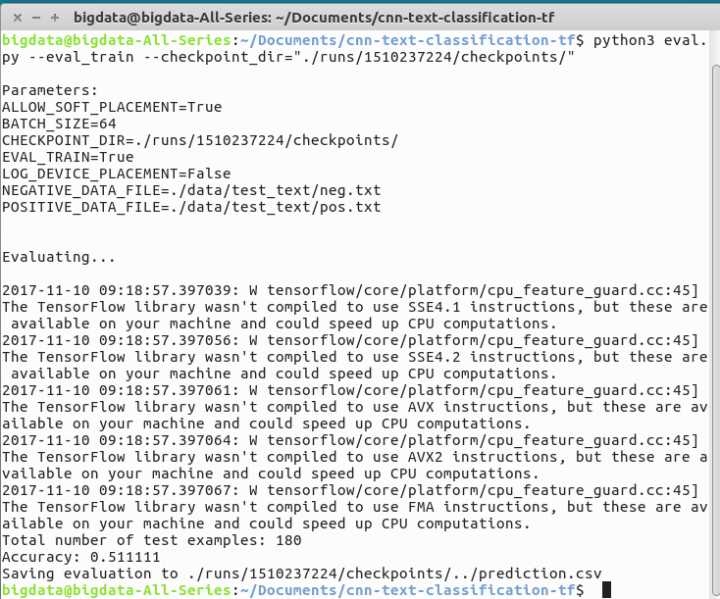
    模型评估:
    实验三,准备换一下数据集,用这里的数据集来跑这个模型: https://zhuanlan.zhihu.com/p/30736422

    3 replies  •  2017-11-10 16:10:05 +08:00
    northisland
        1
    northisland  
       Nov 10, 2017
    很好
    scusjs
        2
    scusjs  
       Nov 10, 2017
    前段时间尝试过几个中文分类的模型,你可以尝试下分词后使用训练好的 word2vec,我这边测试这样的效果会好一些。
    1722332572
        3
    1722332572  
    OP
       Nov 10, 2017
    @scusjs 好的,谢谢。这也是准备尝试的方向。
    About   ·   Help   ·   Advertise   ·   Blog   ·   API   ·   FAQ   ·   Privacy   ·   Solana   ·   2563 Online   Highest 6679   ·     Select Language
    创意工作者们的社区
    World is powered by solitude
    VERSION: 3.9.8.5 · 27ms · UTC 13:40 · PVG 21:40 · LAX 06:40 · JFK 09:40
    ♥ Do have faith in what you're doing.